Gemini 4 Argon API Crash Course
This tutorial shows how to call Google's new Gemini 4 Argon model (model ID "gemini-4-argon") from Node.js using the official @google/genai SDK, moving from a basic hello-world call to controlling the model's thinking_level (low vs high), holding a multi-turn conversation via previous_interaction_id, and finally using background mode to have the model build a playable Breakout game in a single HTML file. It requires a Google account, an API key from Google AI Studio tied to a billing-enabled project, Node.js with "type": "module" set in package.json, and a .env file storing the key as GEMINI_API_KEY. The video ends with a working game.html Breakout game generated from one background prompt, plus a short on-camera segment with Google DeepMind's Jack Wetherspoon and a teammate discussing the model.
Goal [00:02]: Google released Gemini 4 Argon, described as Google's most capable model yet, built for complex coding, math, and science tasks.
- Goal [00:12]: the video teaches using Gemini 4 Argon, controlling how hard it thinks, holding a back-and-forth conversation with it, and having it build a game in a few small JavaScript files.
- Prereq [02:05]: set up by going to Google AI Studio, signing in with a Google account, clicking "Get API Key," and creating a key tied to a project with billing enabled, or Argon will turn requests down.
- Step [01:10]: the model is called from code using model ID string "gemini-4-argon" via the GoogleGenAI client's interactions.create method.
- Step [01:23]: Argon thinks before answering, controlled by a thinking_level setting with three options: low, medium, or high, with medium as the default.
+ 48 more takeaways
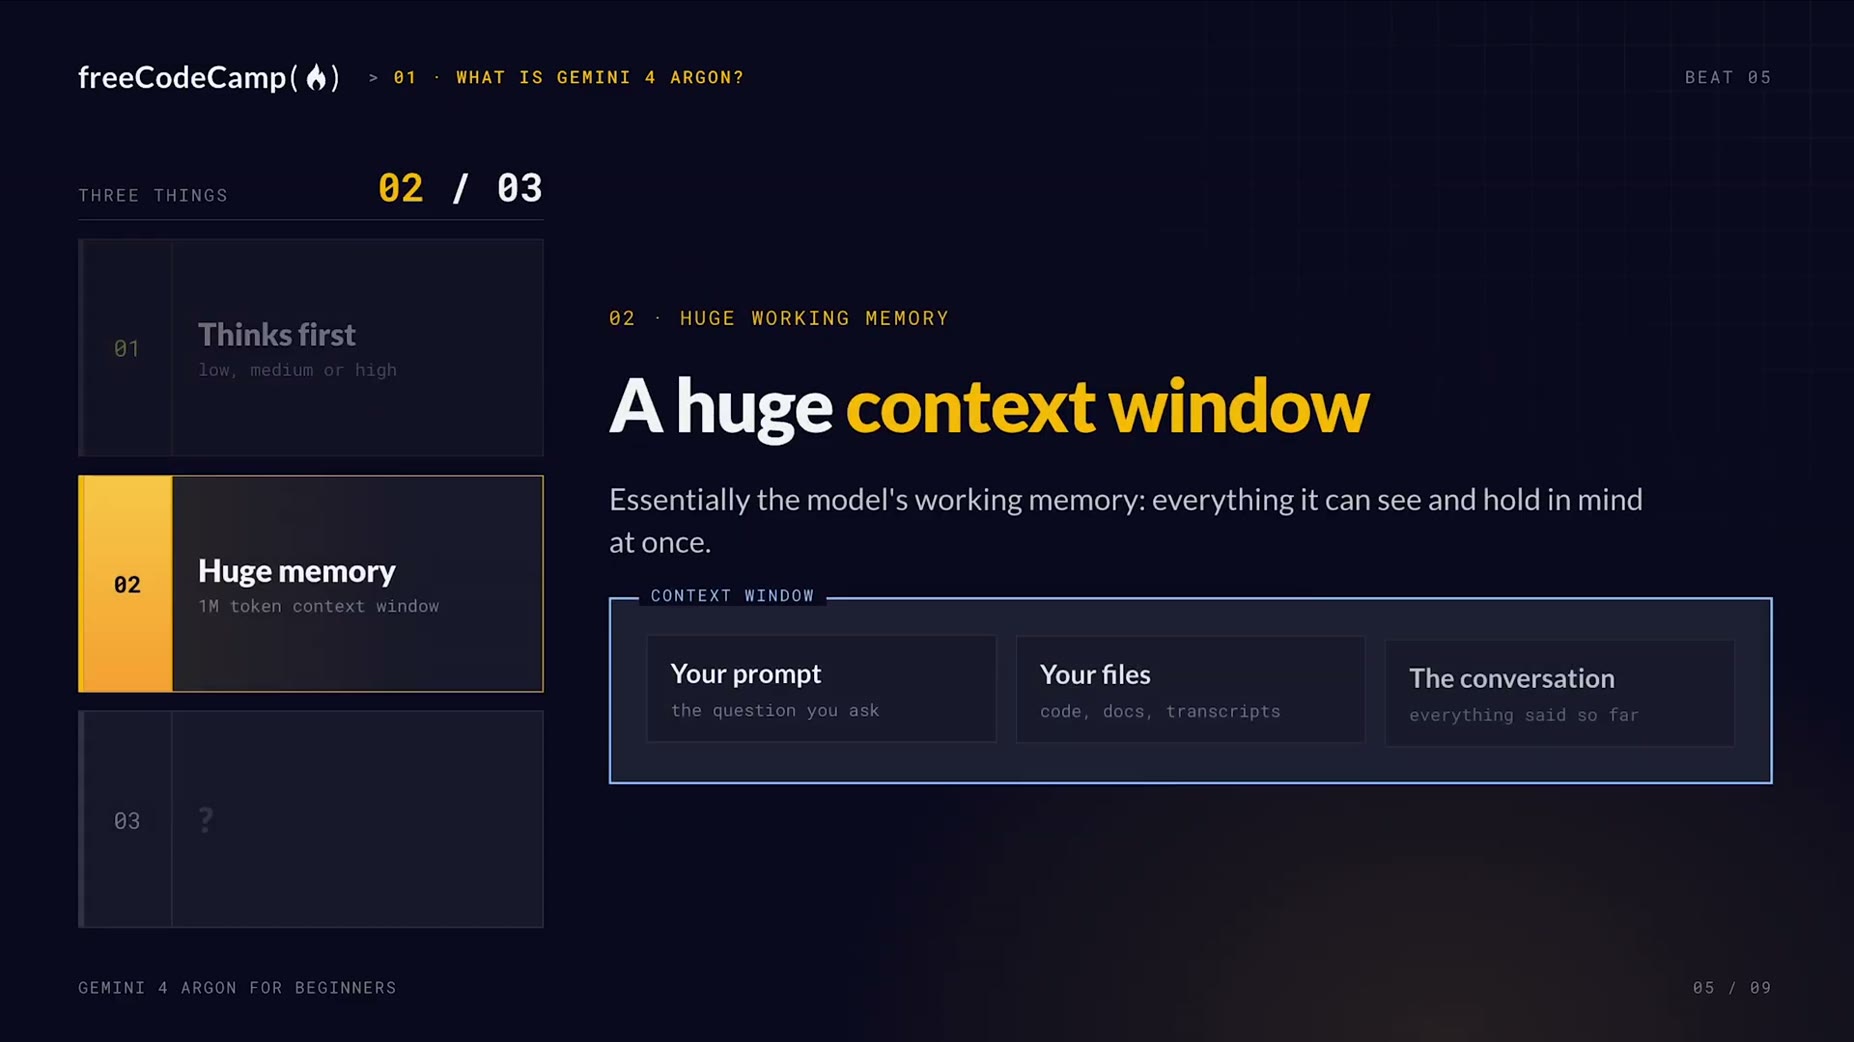
- Step [01:36]: the context window is described as the model's working memory covering everything it can see and hold at once.
- Step [01:42]: the context window is just over 4 million tokens, shared between what you send in, what the model thinks, and what it writes back.
- Step [01:55]: Argon can run in the background, letting you hand it a large job (e.g. "Build a Breakout game") with background: true and come back later for results.
- Step [02:32]: the project uses Google's official SDK, the package @google/genai.
- Step [02:41]: adding "type": "module" to package.json enables import and top-level await.
- Step [02:49]: a .env file holds the key under the name GEMINI_API_KEY.
- Step [02:56]: the SDK automatically looks for the GEMINI_API_KEY environment variable, so the key is never touched in code.
- Step [03:02]: the .env file is added straight into .gitignore.
- Step [03:11]: hello.js imports GoogleGenAI and creates a client with an empty options object since the key is found from the environment.
- Step [03:22]: the code calls client.interactions.create, passing model "gemini-4-argon" and an input prompt.
- Command [03:49]: node --env-file=.env hello.js is used to load the key, producing the first response from Gemini for Argon.
- Output [03:55]: Gemini for Argon responds comparing an API to a waiter at a restaurant, acting as a messenger between code and existing programs.
- Note [03:59]: the presenter says this call pattern is the same for everything else in the course, just with extra options.
- Step [04:06]: by default the model thinks at a 'medium' thinking level before responding.
- Step [04:21]: a buggy averageScore function is used as a test case, passing scores 80, 90, and 100 but printing NaN instead of the expected 90.
- Step [04:48]: a generation_config object with a thinking_level field is the only new addition needed to control thinking level.
- Pitfall [05:07]: the bug is the loop using <= instead of <, causing it to read an undefined array index and turn the sum into NaN.
- Result [05:07]: at thinking_level low, Argon found the bug in 6.3s with 0 thinking tokens.
- Result [05:07]: at thinking_level high, Argon found the same bug in 11.8s with 629 thinking tokens.
- Note [05:27]: Google's advice is to try a task at all three thinking levels and pick the lowest one that still gives good answers.
- Note [05:34]: thinking tokens are billed as output tokens, so more thinking means slower and more expensive responses.
- Step [05:53]: in chat.js, the model is first asked to fix the bug, then followed up with a question about what should happen if the array is empty.
- Step [06:04]: the second interactions.create call passes previous_interaction_id set to the first interaction's id to continue the conversation.
- Note [06:10]: Google keeps the conversation state on their side, so the follow-up picks up exactly where the first request left off, adding a check to avoid dividing by zero.
- Note [06:21]: passing previous_interaction_id is described as essentially the one line needed to give a chatbot memory.
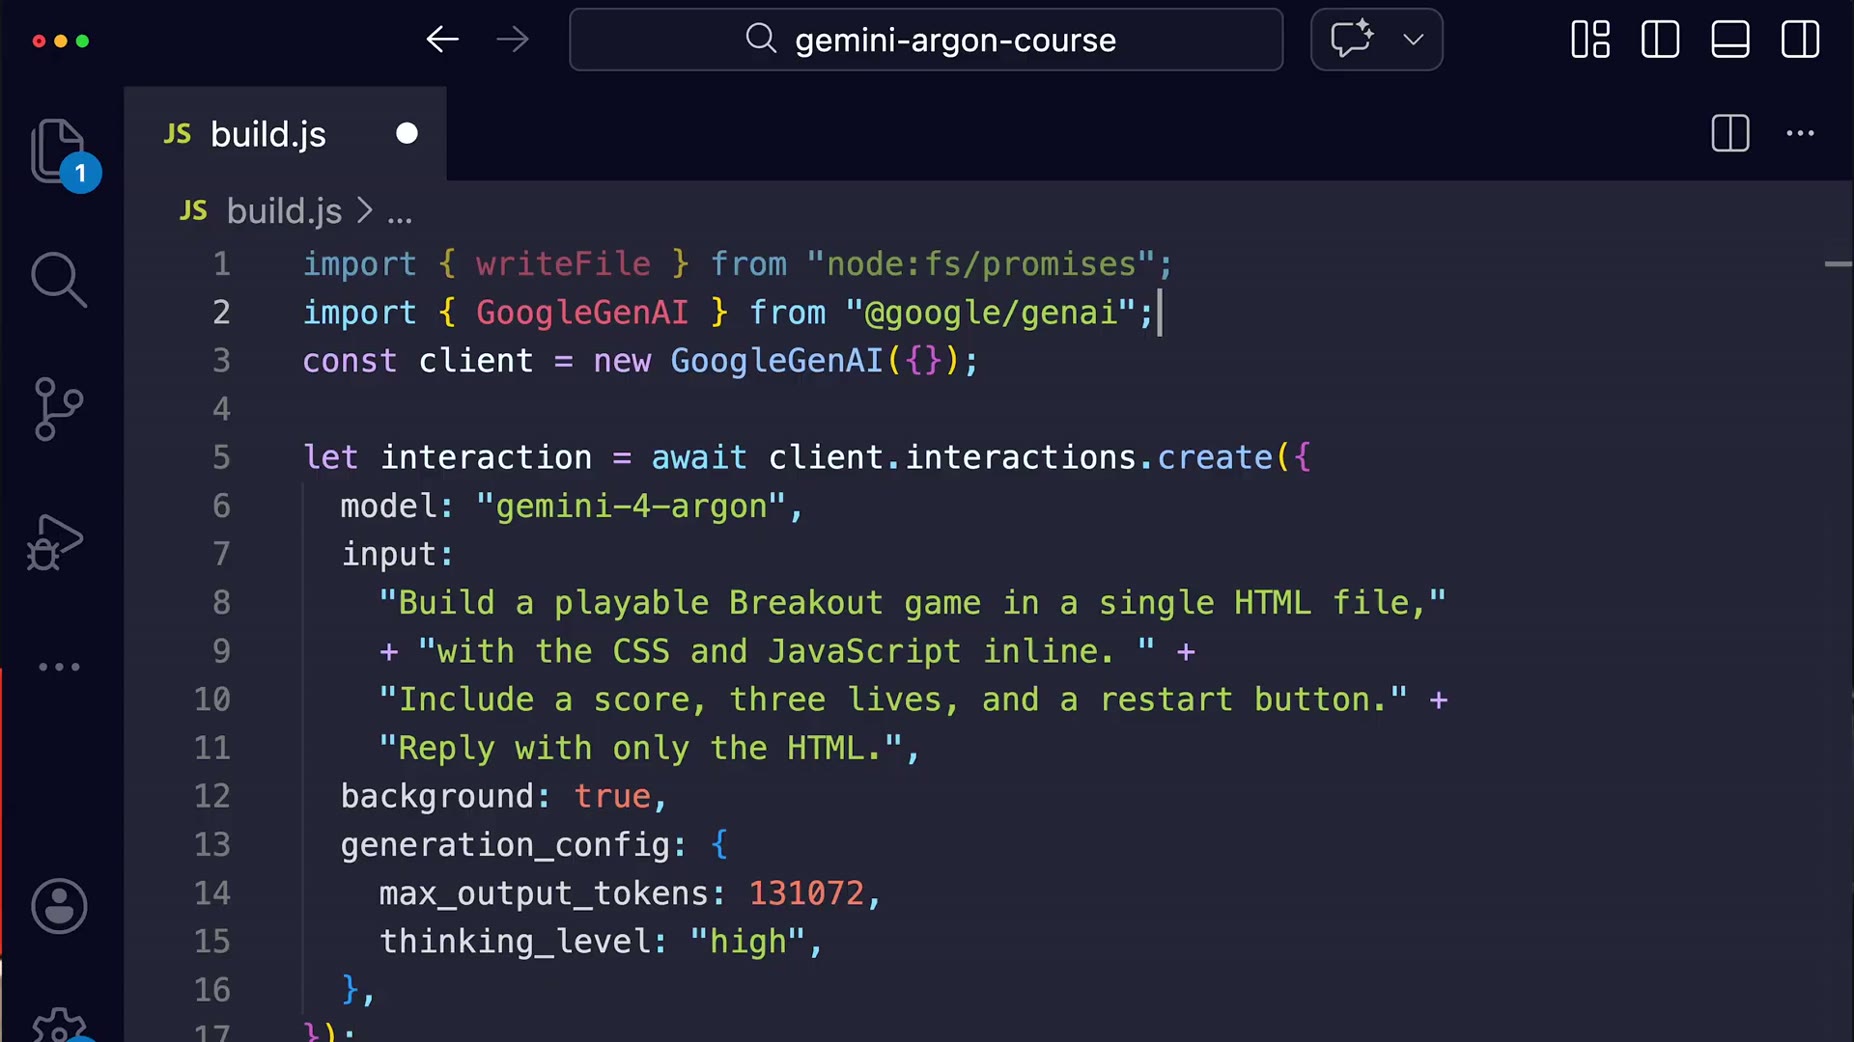
- Step [06:31]: using background mode, Argon is asked to build a playable Breakout game in a single HTML file with inline CSS and JavaScript, a score, three lives, and a restart button.
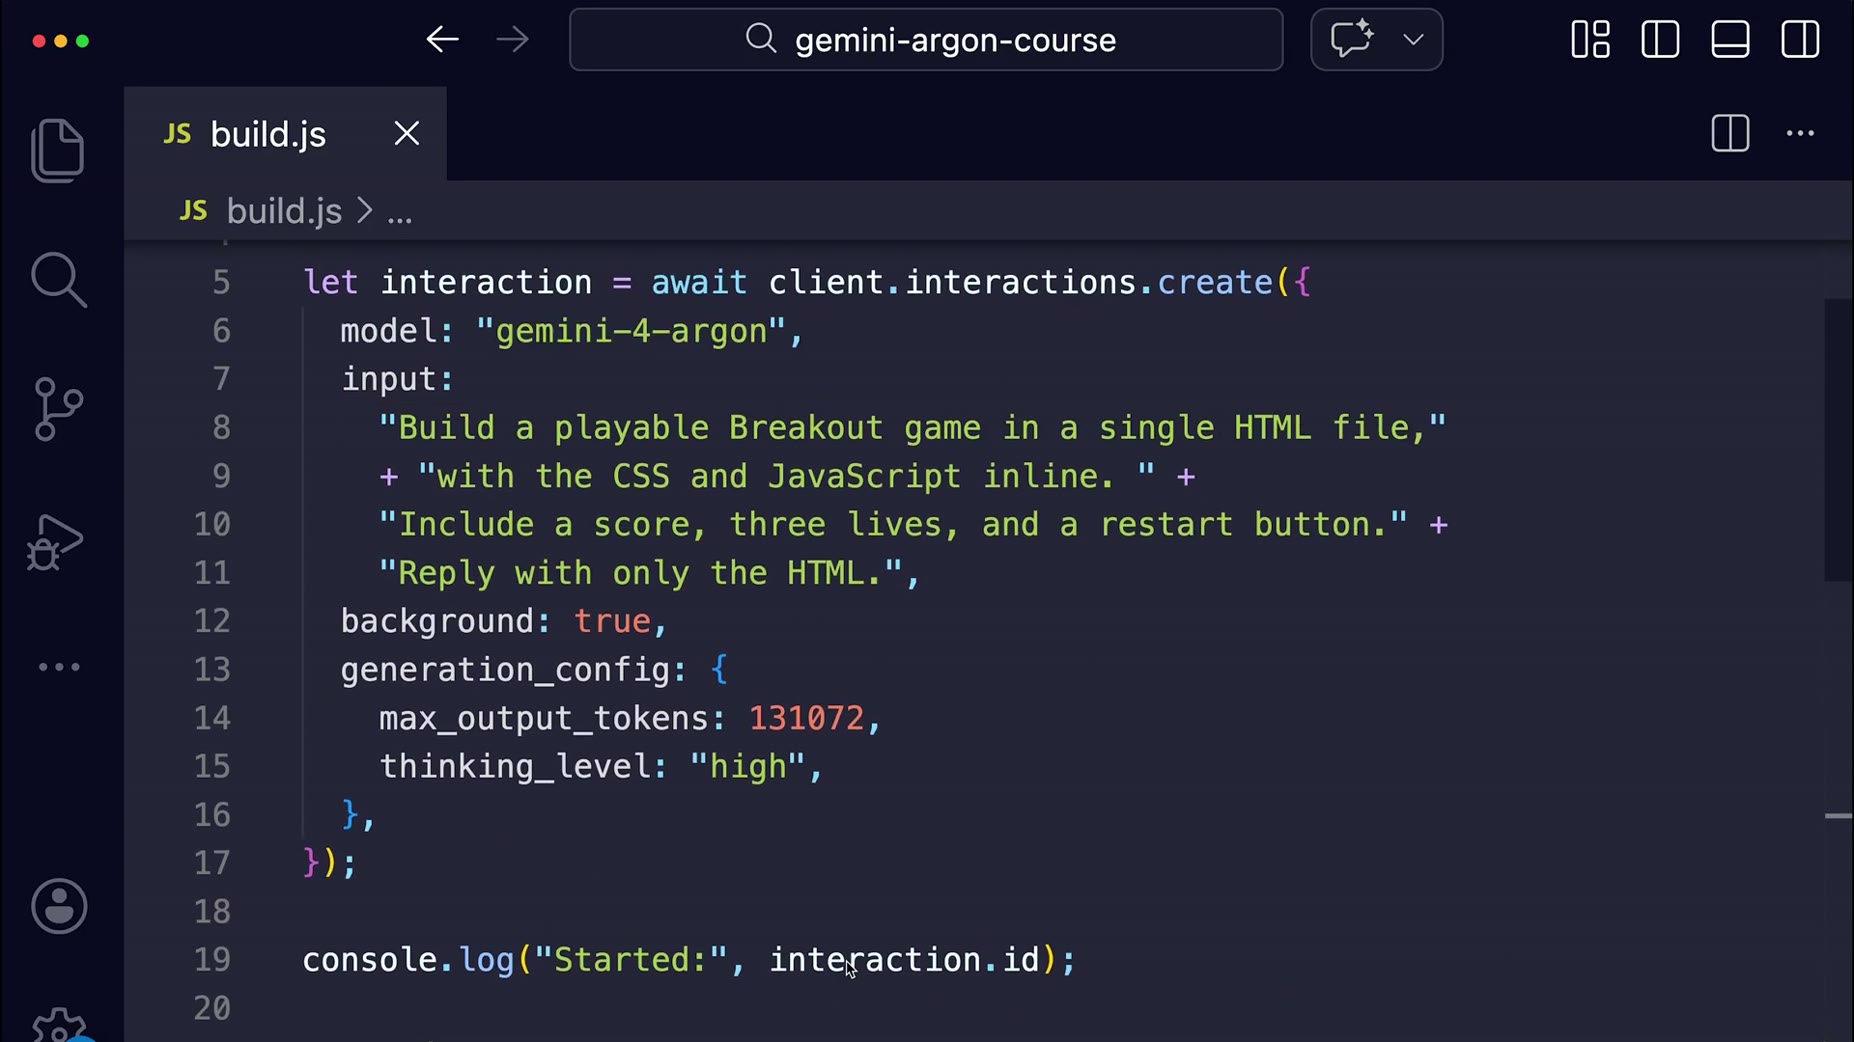
- Step [06:42]: background mode uses the same create call with three changes.
- Config [06:48]: background is set to true, thinking_level set to "high", and max_output_tokens raised to 131,072.
- Pitfall [06:56]: without max_output_tokens set, background mode stops at about 64,000 tokens.
- Step [07:03]: the create call returns an interaction with a status of either queued or in progress.
- Step [07:09]: the code checks back every five seconds using client.interactions.get.
- Step [07:14]: once the job finishes, the model's answer is split across multiple steps.
- Step [07:18]: the script joins the text from all model_output steps and writes the result to game.html.
- Note [07:23]: the work happens on Google servers rather than the presenter's laptop.
- Note [07:28]: you can close your laptop and come back later while the interaction runs.
- Final result [07:36]: the result is a working Breakout game with a score, lives, and a restart button, all from one prompt.
- Note [07:57]: example apps shown built with Gemini 4 Argon include WizardChess3D, Chaco Canyon 3D, ArgonTennis, Pocket World Terrarium, and Isometric Town Builder.
- Commentary [07:51]: Jack Wetherspoon introduces himself as being on the developer experience team at Google DeepMind.
- Commentary [07:59]: Jack Wetherspoon says they just launched Gemini 4 Argon.
- Commentary [08:02]: Jack says his favorite thing about the latest Gemini model is that you can throw ideas at it and it reasons through to an elegant solution you might not have fully thought through yourself.
- Commentary [08:35]: Genevieve, a teammate of the speaker, did a launch demo in the blog post for Gemini 3 (referred to as Argonne) where she took a picture of her apartment desk.
- Commentary [08:44]: she asked the model to turn the desk photo into a 3D racetrack.
- Commentary [08:50]: the model used Blender via the Blender MCP to build the 3D components and pulled in Nano Banana to generate textures for the car and background.
- Commentary [09:02]: the model also searched the web for motor sounds and added its own audio to the resulting game.
- Commentary [09:23]: the speaker says Argonne is their favorite model for creative writing and general writing compared to other models.
- Commentary [09:33]: they say the model is strong at weaving a narrative that doesn't sound like AI or have typical model quirks that let readers guess which model wrote something.
- Commentary [09:53]: the team spent research time training the model specifically on writing.
- Final state [10:11]: the video covered using the Gemini/Argonne API to create programs and a game, with links to code and more in the description.
import { writeFile } from "node:fs/promises";
import { GoogleGenAI } from "@google/genai";

const client = new GoogleGenAI({});

let interaction = await client.interactions.create({
  model: "gemini-4-argon",
  input:
    "Build a playable Breakout game in a single HTML file," +
    "with the CSS and JavaScript inline. " +
    "Include a score, three lives, and a restart button." +
    "Reply with only the HTML.",
  background: true,
  generation_config: {
    max_output_tokens: 131072,
    thinking_level: "high",
  },
});

console.log("Started:", interaction.id);

while (interaction.status === "in_progress" [...] interaction.status === "queued") {
  await new Promise((resolve) => setTimeout(resolve, 50o0));
  interaction = await client.interactions.get(interaction.id);
  console.log("status:", interaction.status);
}

const text = interaction.steps
  .filter((step) => step.type === "model_output")
  .flatMap((step) => step.content ?? [])
  .filter((content) => content.type === "text")
  .map((content) => content.text)
  .join("");

const html = text.replace(/^[...](?:html)?\s*/i, "").replace(/[...]\s*$/, "");

await writeFile("game.html", html);
console.log("Saved game.html. Usage:", interaction.usage);Find the bug in this code and give me the fixed version:
${buggyCode}Great. Now what should happen if the array is empty? Update the function to handle that.
Explain what an API is to someone writing their first line of code. Keep it to three sent[...]
import { GoogleGenAI } from "@google/genai";
import { buggyCode } from "./buggy-code.js";

const client = new GoogleGenAI({});

async function hunt(level) {
  const start = Date.now();

  const interaction = await client.interactions.create({
    model: "gemini-4-argon",
    input: `Find the bug in this code and explain it in one short paragraph:\n${[...]}`,
    generation_config: {
      thinking_level: level,
    },
  });

  const seconds = ((Date.now() - start) / 1000).toFixed(1);
  console.log(`\n--- thinking_level: ${level} (${seconds}s) ---`);
  console.log("Thinking tokens:", interaction.usage?.total_thought_tokens);
  console.log(interaction.output_text);
}

await hunt("low");
await hunt("high");How this brief was shaped: Deep-Dive (coding / tutorial / how-to) · confidence High
Transcript lays out a goal and step by step plan (API key, npm init, SDK install, env file, thinking levels, chat, build a game) and OCR shows a code editor with buggy-code.js, think.js, chat.js plus terminal output walking through an off-by-one bug fix, matching a coding tutorial replicate-the-result shape.
The lens sets this brief's structure, never its facts — every claim is held to the same citation and fact-check standard.